robots.txt and llms.txt: Helping Crawlers Read the Right Pages
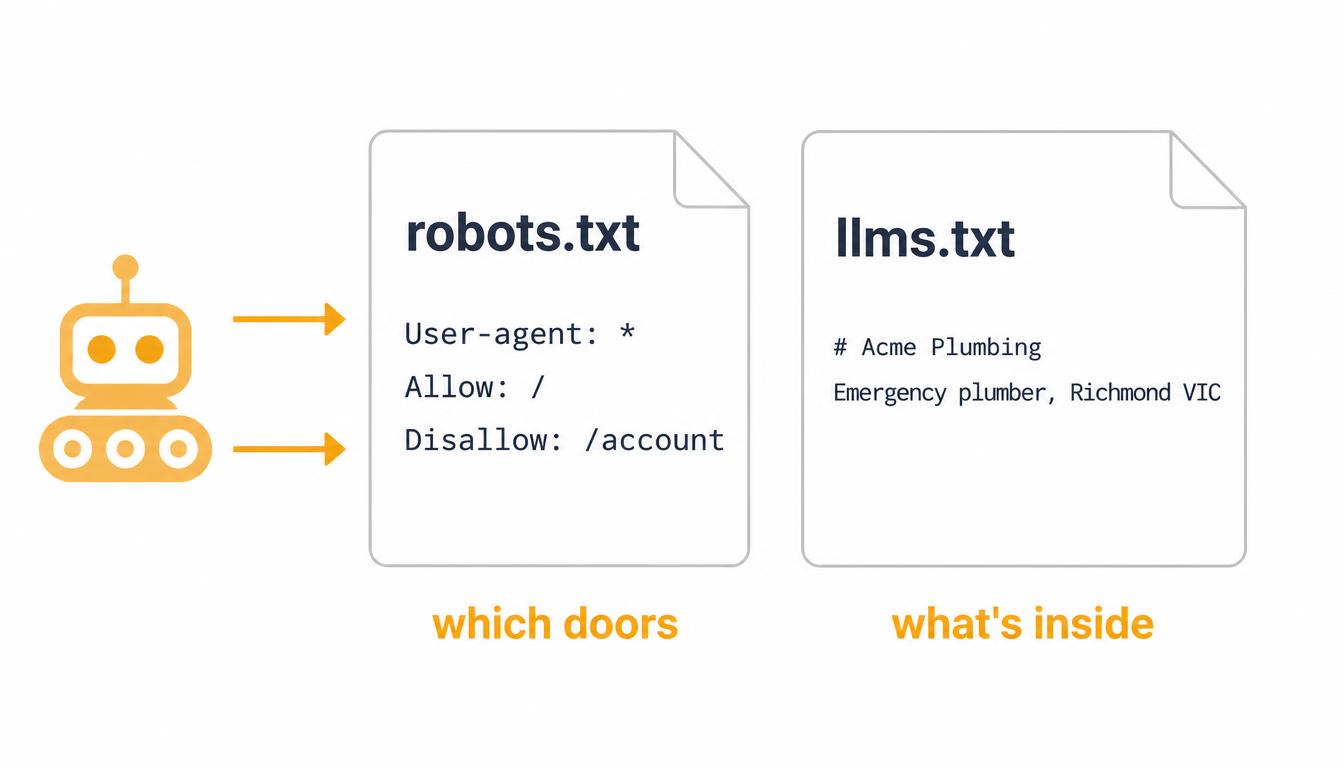
robots.txt gives crawlers access instructions for your website, while llms.txt is an emerging way to present a concise, human-readable guide to the content you want AI systems to understand.
Why they matter
Crawlers cannot use content they cannot reach, and unrestricted access is not always the right answer.
A well-considered robots.txt can steer compliant crawlers away from private, duplicate or low-value areas while keeping important public pages accessible. A mistake can also block the pages you most want discovered.
llms.txt serves a different purpose. It can summarise your organisation and point to useful public resources in a clean text format. It is an emerging convention rather than a guaranteed ranking or citation mechanism, so it should support your website rather than replace clear pages and structured data.
Keep reading with a free account
The rest of this guide covers how to apply it, the mistakes to avoid, and the quick answers. Free to read — no card required.
Continue with a free account